Research project
PawCT: End-to-End Choral Transcription into Separate SATB Note Tracks
1UNSW · 2UWA · 3Queen Mary University of London · 4Great Bay University
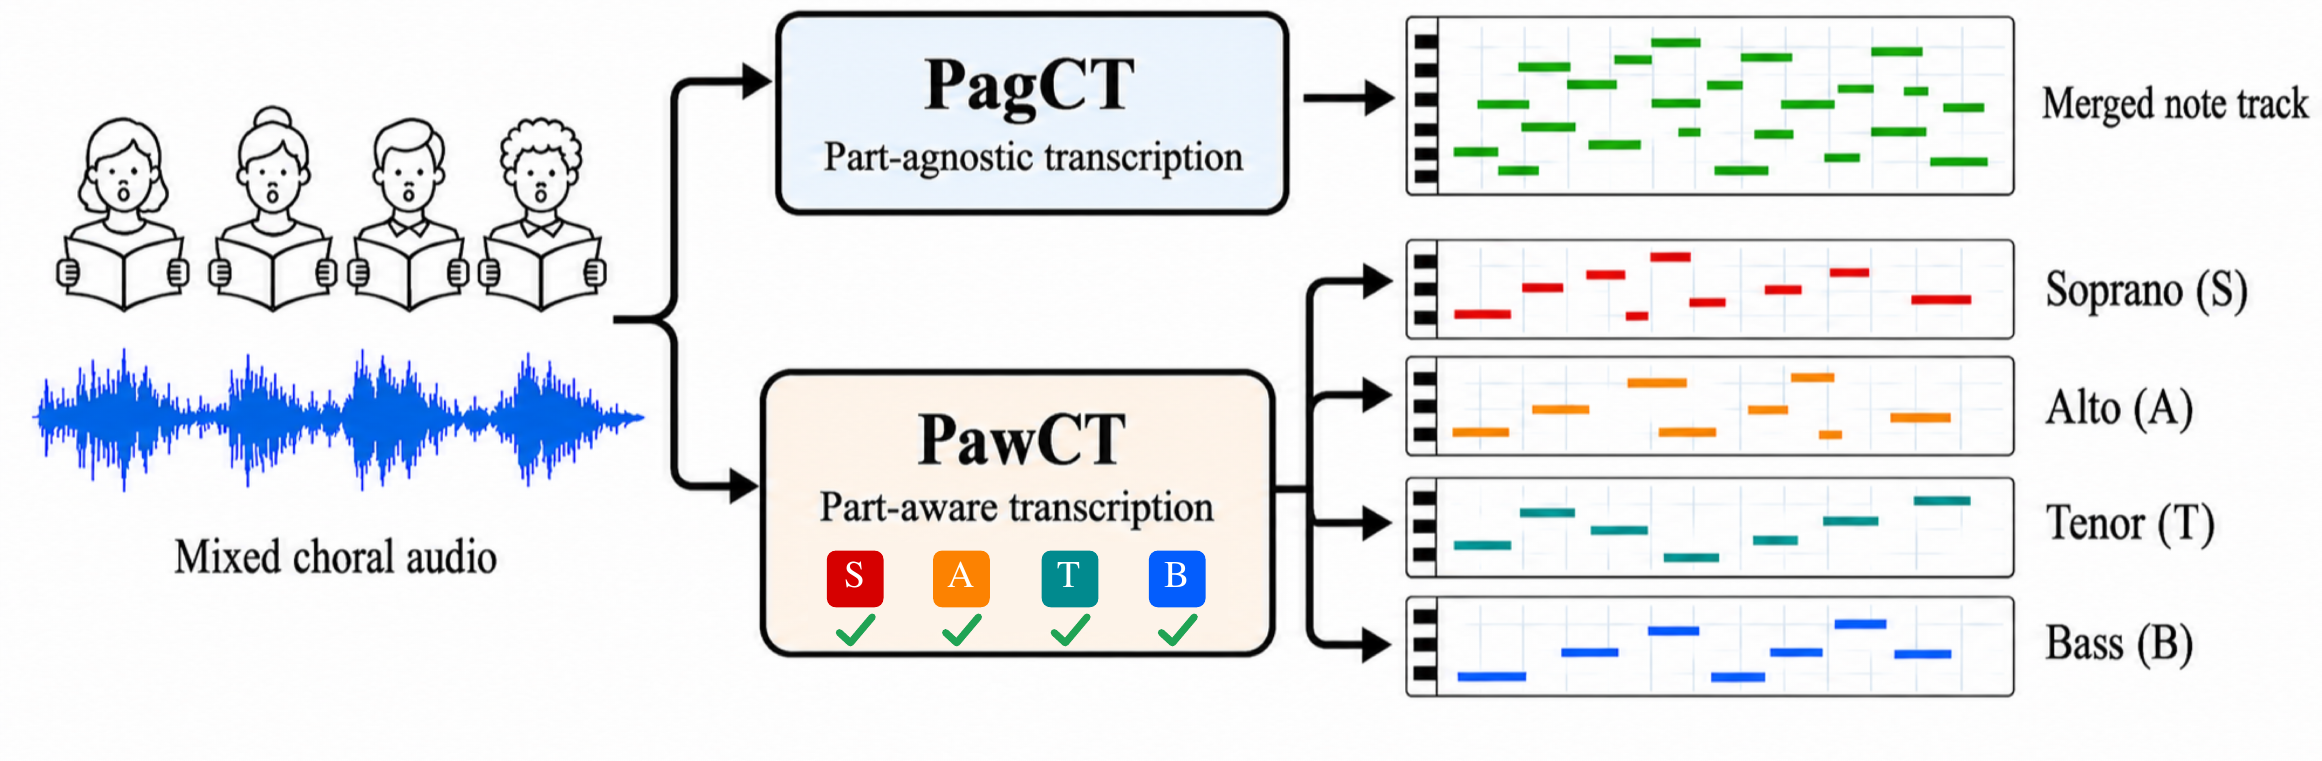
Most choral transcription systems return one merged stream of notes. PawCT identifies which sections are singing and writes a separate MIDI track for soprano, alto, tenor, and bass.
From one choir recording to four usable parts
Performance at a glance
Bold: best. Underlined: second best.
Full paper results
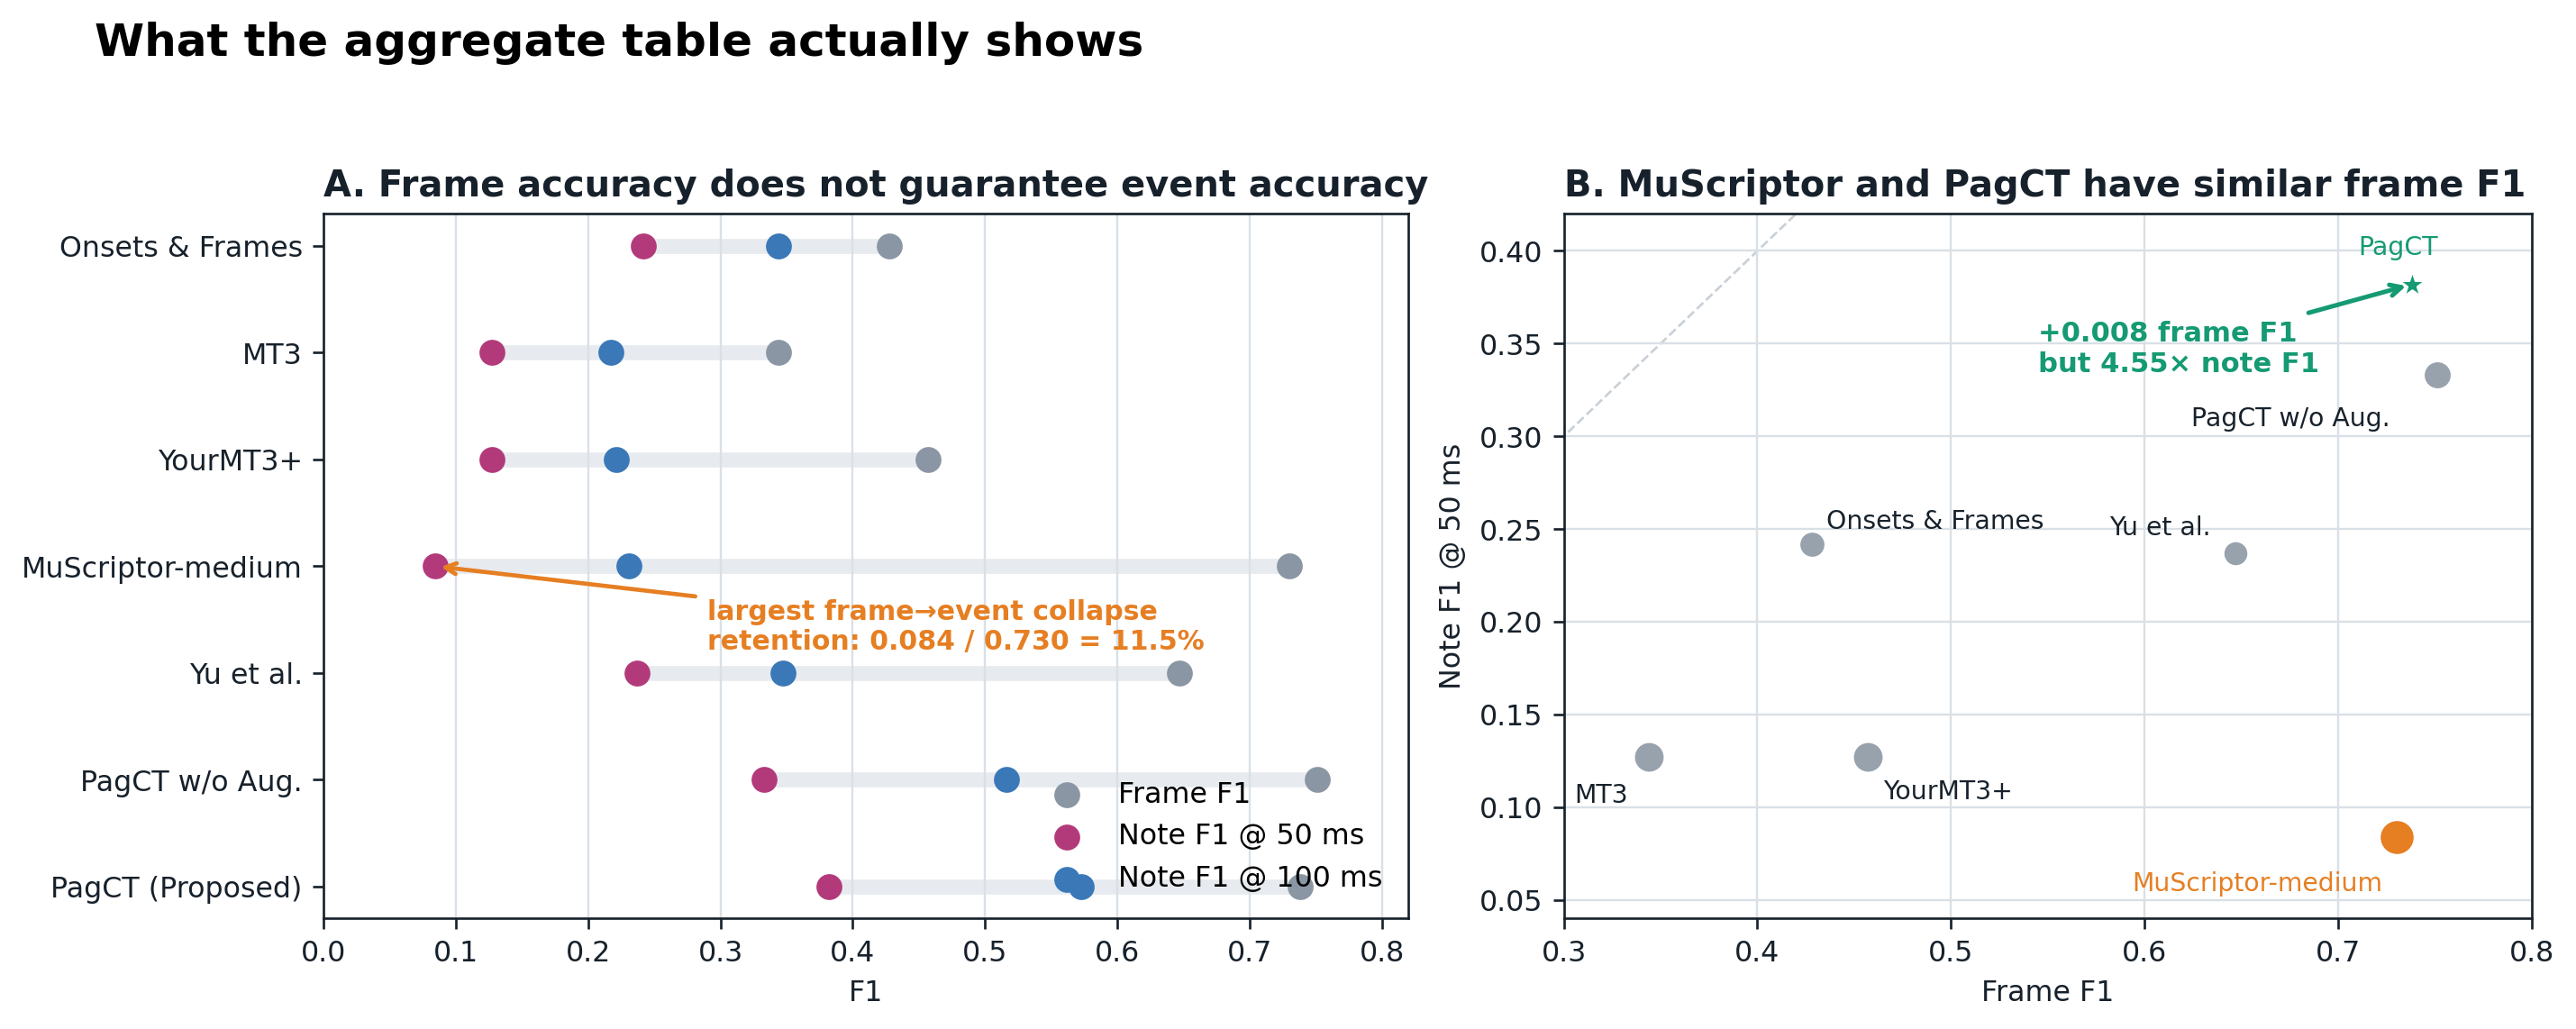
Table 1 · Part-agnostic transcription on YouChorale
| Model | #Params | Frame | Onset (50 ms) | Onset (100 ms) | ||||||
|---|---|---|---|---|---|---|---|---|---|---|
| P | R | F1 | P | R | F1 | P | R | F1 | ||
| Onsets and Frames | 6.79M | 0.806 | 0.326 | 0.428 | 0.450 | 0.178 | 0.242 | 0.688 | 0.248 | 0.344 |
| MT3 | 44.7M | 0.590 | 0.243 | 0.344 | 0.117 | 0.148 | 0.127 | 0.200 | 0.255 | 0.217 |
| YourMT3+ | 45.8M | 0.529 | 0.423 | 0.457 | 0.145 | 0.119 | 0.127 | 0.252 | 0.207 | 0.221 |
| MuScriptor-medium | 307M | 0.720 | 0.745 | 0.730 | 0.086 | 0.083 | 0.084 | 0.236 | 0.228 | 0.231 |
| Yu et al. | 4.23M | 0.678 | 0.619 | 0.647 | 0.251 | 0.232 | 0.237 | 0.366 | 0.341 | 0.347 |
| PagCT w/o Aug. | 14.84M | 0.690 | 0.833 | 0.751 | 0.346 | 0.329 | 0.333 | 0.539 | 0.506 | 0.516 |
| PagCT | 14.84M | 0.626 | 0.909 | 0.738 | 0.398 | 0.378 | 0.382 | 0.597 | 0.569 | 0.573 |
Table 2 · Part-aware SATB transcription on YouChorale · Note F1 @ 50 ms
| Model | Soprano | Alto | Tenor | Bass | Average | VA Rate (%) | ||||||
|---|---|---|---|---|---|---|---|---|---|---|---|---|
| Frame | Note | Frame | Note | Frame | Note | Frame | Note | Frame | Note | Frame | Note | |
| YourMT3+★ | 0.371 | 0.083 | 0.297 | 0.068 | 0.294 | 0.073 | 0.371 | 0.093 | 0.333 | 0.079 | 72.87 | 62.20 |
| Yu et al.★ | 0.528 | 0.183 | 0.451 | 0.151 | 0.436 | 0.138 | 0.560 | 0.186 | 0.494 | 0.165 | 76.35 | 69.62 |
| PagCT + Post-VA | 0.501 | 0.180 | 0.439 | 0.145 | 0.447 | 0.156 | 0.568 | 0.219 | 0.489 | 0.175 | 66.26 | 45.81 |
| PawCT w/o union-loss | 0.417 | 0.192 | 0.338 | 0.169 | 0.343 | 0.178 | 0.419 | 0.222 | 0.379 | 0.190 | 51.36 | 49.74 |
| PawCT | 0.530 | 0.228 | 0.430 | 0.191 | 0.429 | 0.197 | 0.552 | 0.252 | 0.458 | 0.217 | 62.06 | 56.81 |
| PawCT-RP | 0.542 | 0.210 | 0.453 | 0.185 | 0.458 | 0.194 | 0.585 | 0.247 | 0.510 | 0.209 | 69.11 | 54.71 |
| PawCT-RP-OC | 0.535 | 0.231 | 0.447 | 0.197 | 0.451 | 0.208 | 0.578 | 0.264 | 0.503 | 0.225 | 68.16 | 58.90 |
Table 3 · Cross-dataset part-aware note F1 @ 50 ms
| Dataset | Model | Soprano | Alto | Tenor | Bass | Average |
|---|---|---|---|---|---|---|
| CSD n = 3 | PagCT + Post-VA | 0.073 | 0.122 | 0.131 | 0.143 | 0.118 |
| PawCT | 0.140 | 0.175 | 0.183 | 0.145 | 0.172 | |
| PawCT-RP-OC | 0.145 | 0.223 | 0.199 | 0.130 | 0.174 | |
| Cantoría n = 14 | PagCT + Post-VA | 0.179 | 0.115 | 0.085 | 0.084 | 0.115 |
| PawCT | 0.240 | 0.239 | 0.275 | 0.328 | 0.271 | |
| PawCT-RP-OC | 0.329 | 0.273 | 0.300 | 0.348 | 0.313 |
Model Overview
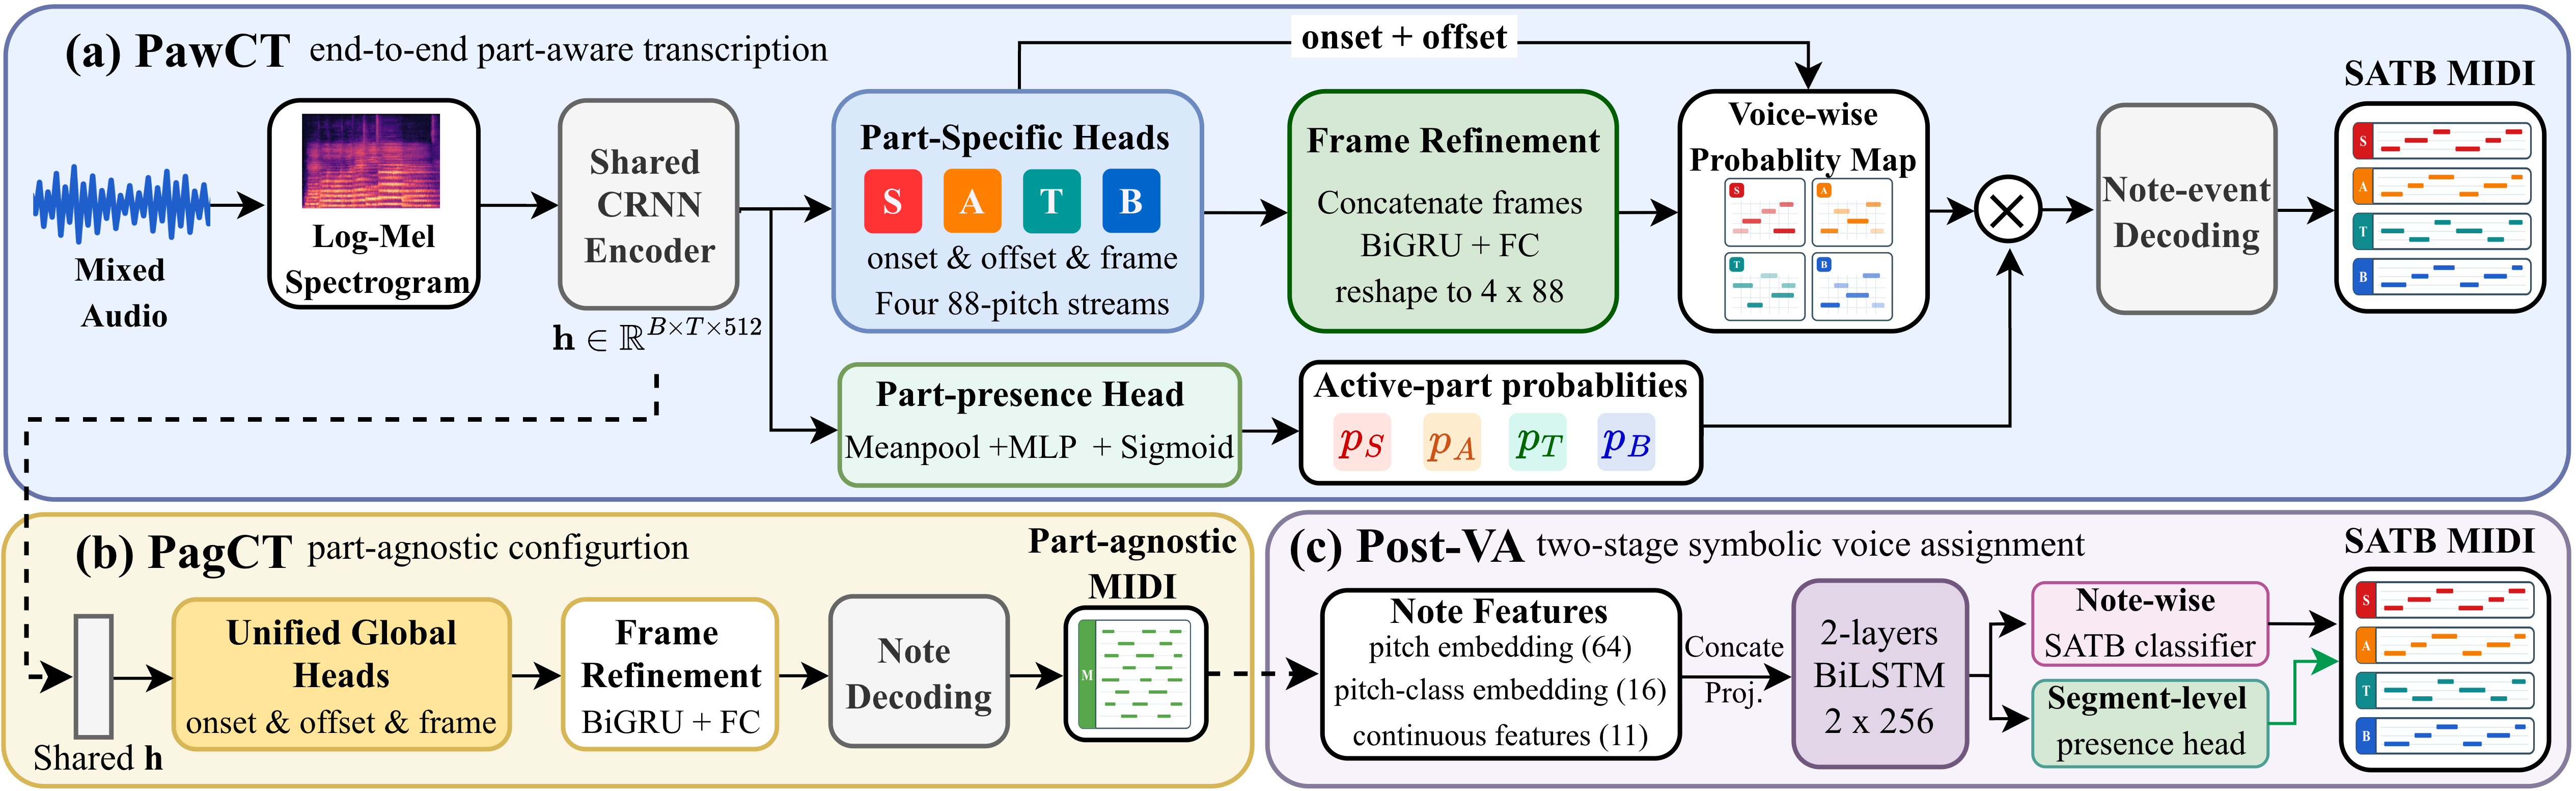
PawCT detects notes and assigns them to vocal parts in one model. A global training signal keeps the complete pitch content intact, while pitch range and melodic continuity help maintain consistent SATB lines.
Listen to the transcription
This 35-second excerpt of Exsultate Deo lets you compare the part-agnostic ground truth with merged predictions from our PagCT model, MuScriptor-medium, and Yu & Duan (2024). PawCT additionally returns four independently playable vocal parts.
Loading the reference and model outputs…
Merged transcription
All annotated or detected notes share one track.
- F1@50 ms
- —
- F1@100 ms
- —
- F1@50 ms
- 0.433
- F1@100 ms
- 0.668
- F1@50 ms
- 0.037
- F1@100 ms
- 0.240
- F1@50 ms
- 0.017
- F1@100 ms
- 0.030
Separate vocal parts
Play each PawCT output on its own, or compare it with post-hoc assignment.
View the full piano-roll comparison
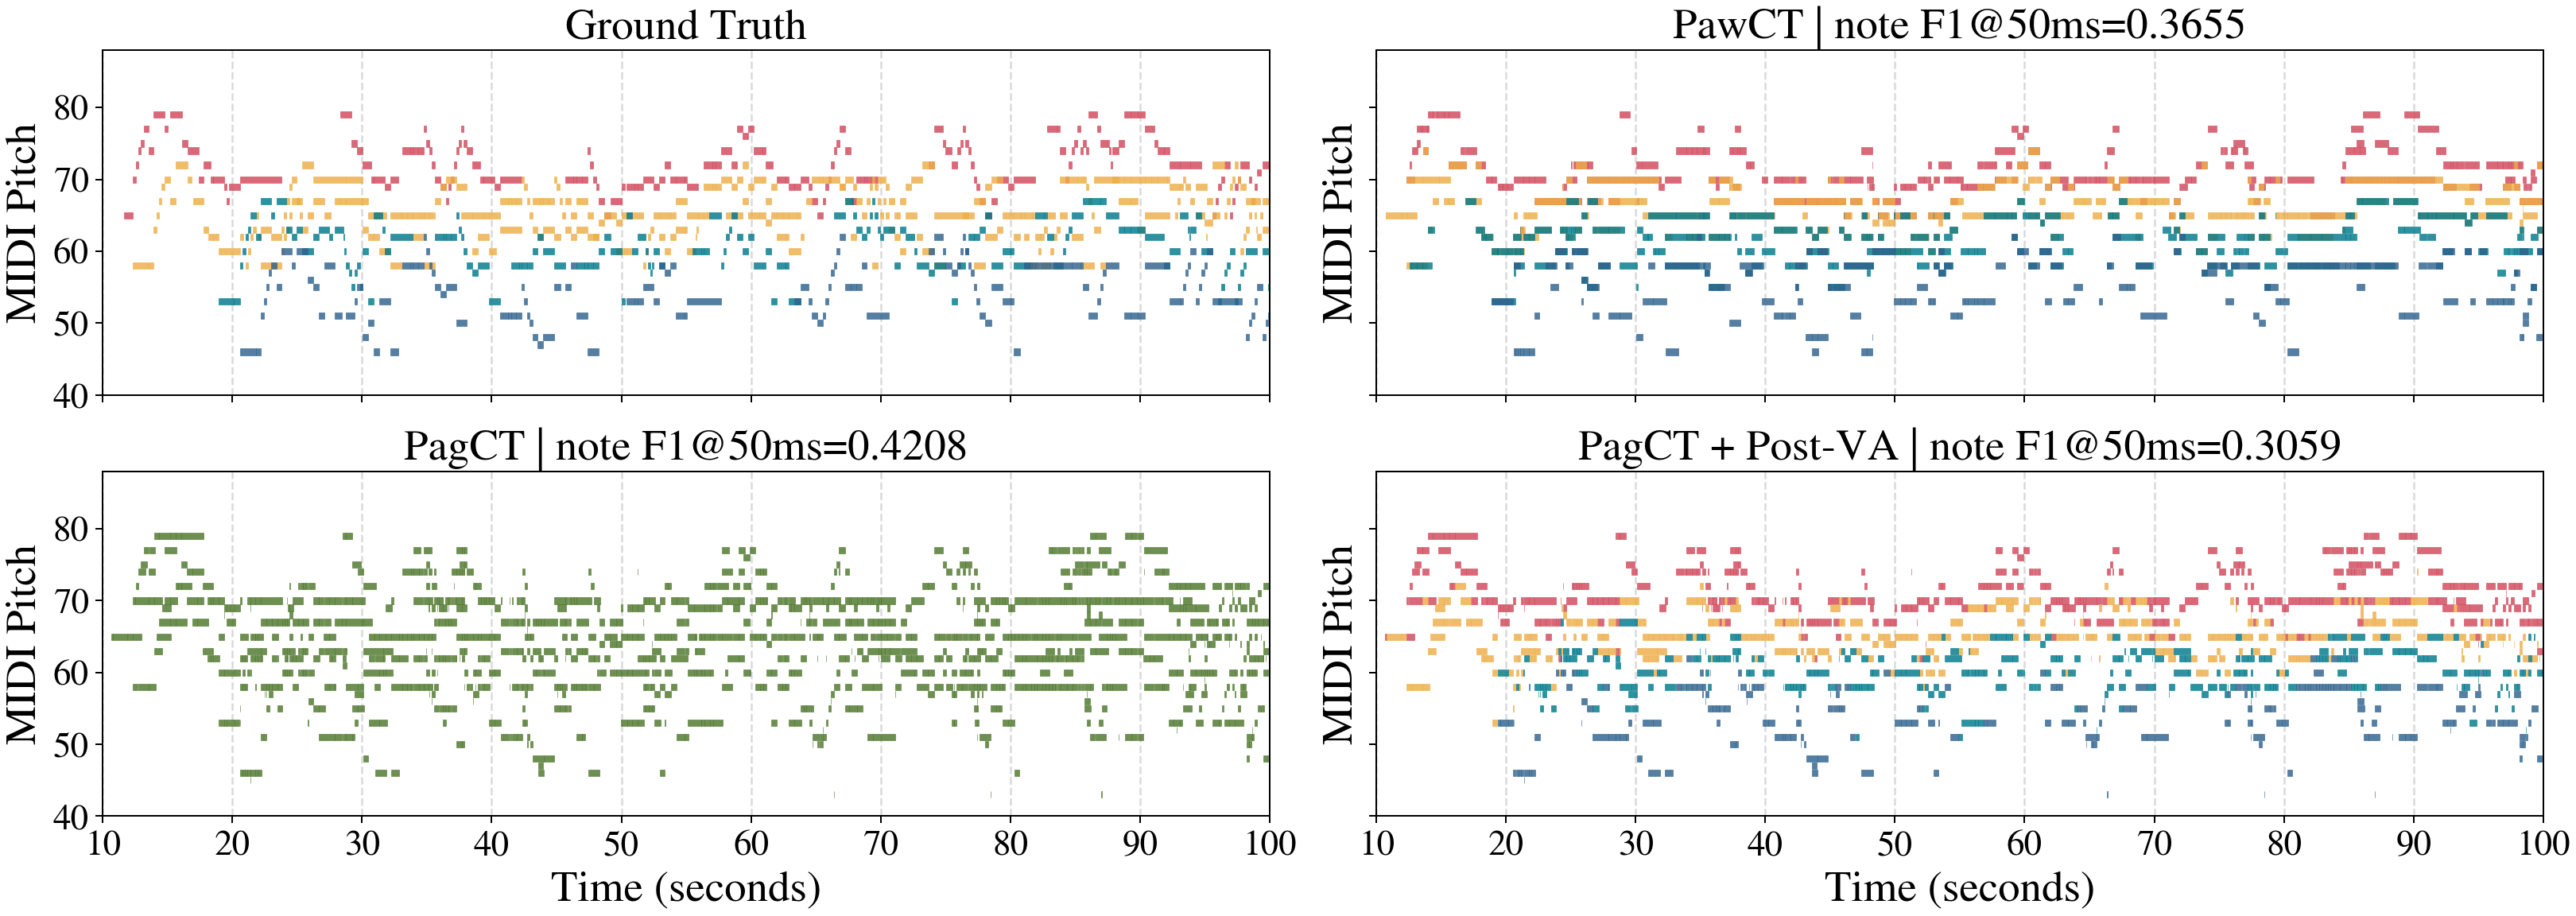
References
- S. Rouard, M. Krause, A. Roebel, C.-J. Simon-Gabriel, and A. Défossez, “MuScriptor: An Open Model for Multi-Instrument Music Transcription,” arXiv:2607.08168 [cs.SD], 2026. Paper · Code · Model
- H. Yu and Z. Duan, “Note-Level Transcription of Choral Music,” in Proceedings of the 25th International Society for Music Information Retrieval Conference (ISMIR), pp. 182–188, 2024. Paper · Code
Error analysis
From pitch activity to note events
MuScriptor-medium and PagCT achieve similar frame F1 (0.730 vs. 0.738), but PagCT obtains substantially higher 50-ms note F1 (0.382 vs. 0.084). This suggests that the main gap lies in localizing note events precisely rather than detecting sustained pitch activity.